Custom AI agent · Documents & Data
AI PDF Data Extraction Agent
Turn complex PDFs into usable records your team can review.
Extract structured fields from PDFs, preserve source context, and route uncertainty before it reaches downstream work.
- Less manual copying from PDF documents
- More consistent field and table extraction
- Better traceability from structured data back to source pages
Starting at $300 USD/month
Starting price is $300 USD/month for a tailored solution. Your final proposal defines the scope, deliverables and payment terms. Additional integrations, usage, hosting and ongoing support are scoped and priced before work begins.
What is an AI PDF data extraction agent?
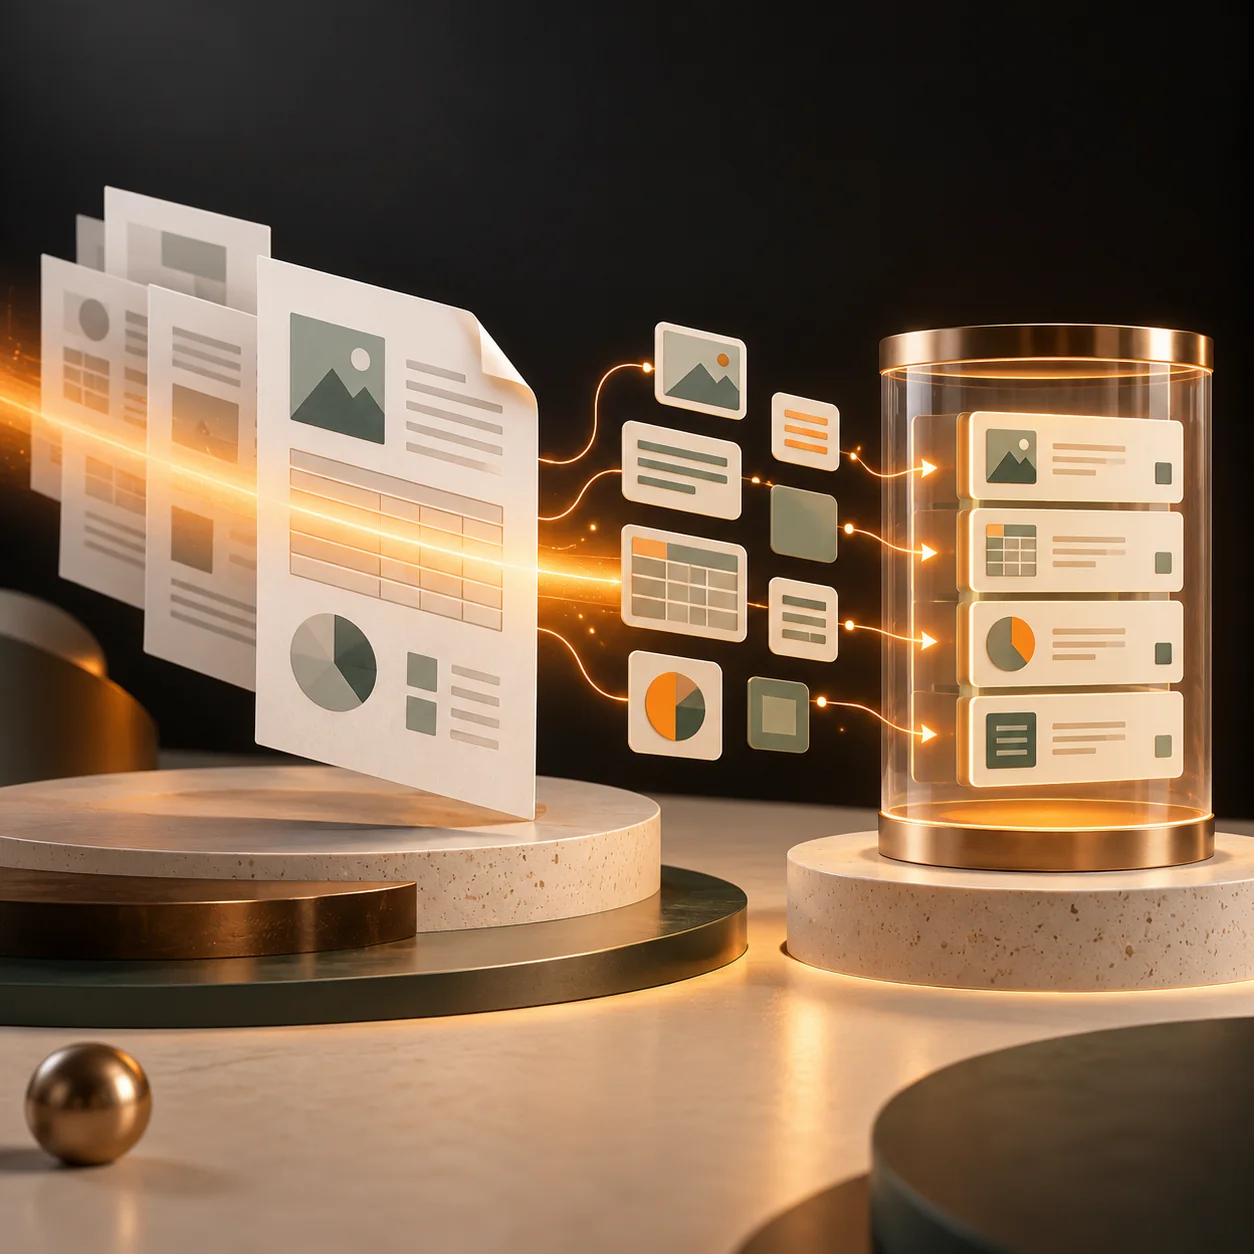
An AI PDF data extraction agent helps your team turn semi-structured PDF documents into usable records. It identifies document type, locates configured fields and tables, extracts the relevant values, preserves page and section context, and flags missing or uncertain information for review. Tranki configures the agent around your document families, schemas, output format, access rules, and downstream systems. It is designed to make extraction auditable rather than treating every PDF as a clean form or silently filling gaps that are not supported by the source.
What it can handle
Document and page classification
Identify supported PDF families, page ranges, sections, attachments, tables, and repeated layouts before applying the correct extraction schema.
Field and table extraction
Capture configured values, line items, dates, identifiers, totals, relationships, and other structured fields while retaining source-page references.
Source-grounded validation
Check required fields, formats, cross-page consistency, and extraction confidence, and highlight values that need human confirmation.
Structured output and routing
Deliver approved JSON, CSV, database, or workflow records with provenance and send incomplete or unsupported documents to the right review path.
Where it can help
Invoice and purchase order processing
Extract supplier, dates, line items, totals, terms, and references before an approved accounts-payable or procurement workflow continues.
Reports and operational packets
Turn recurring PDF reports into structured metrics and records while preserving the page context needed for review and audit.
Applications and case documents
Collect configured fields from forms, attachments, and supporting PDFs, then route missing, conflicting, or sensitive information for human review.
How it works
A step-by-step workflow your team can review before launch.
1. Define document schemas
Tranki maps supported PDF types, target fields, table structures, output schema, source references, validation rules, and exception owners.
2. Read and segment the PDF
The agent identifies pages, sections, tables, and document variants, then applies the appropriate extraction path without altering the original file.
3. Extract and validate
It produces structured values, checks required formats and cross-field consistency, and marks low-confidence or unsupported content instead of guessing.
4. Deliver with provenance
Approved records go to the configured destination with source-page context. Incomplete, sensitive, or ambiguous documents go to the designated human queue.
Built around your business
What we configure
- Document families, schemas, field names, tables, page references, formats, validation rules, and versioned extraction templates
- Output JSON, CSV, database, spreadsheet, ERP, CRM, case, or workflow destinations with review and approval gates
- Redaction, retention, permissions, language coverage, duplicate handling, and exception routing for unsupported or sensitive PDFs
What we need from you
- Representative PDFs for each supported family, including clean, scanned, multi-page, tabular, incomplete, and exception cases
- A target schema, field definitions, output format, source-reference requirement, and human owner for uncertain extraction
- Access to approved document and destination systems with data-retention and sensitive-information rules
Clear boundaries before launch
What it will not do
The agent does not invent missing values, certify the authenticity of a PDF, interpret legal or financial obligations as a decision-maker, expose restricted document content, or overwrite the original source. Scanned, handwritten, password-protected, corrupted, sensitive, or ambiguous files require the configured human review path.
How success is measured
Track extraction completeness, field-level accuracy, table-row accuracy, validation catch rate, source-reference coverage, human correction time, unsupported-file rate, downstream rework, and review acceptance.
Frequently asked questions
What does an AI PDF data extraction agent do?
It identifies supported PDF structures, extracts configured fields and tables, preserves page context, validates the result, and routes uncertainty or exceptions for review.
Can it extract tables from PDFs?
Yes, when the table layout and target schema are defined. It can capture rows and columns, flag alignment issues, and retain the source page for verification.
What output formats can it produce?
The workflow can be tailored to approved JSON, CSV, database, spreadsheet, ERP, CRM, case, or other structured destinations, subject to the selected integration.
Can it process scanned PDFs?
It can work with scanned PDFs when the configured OCR path supports the quality and language involved. Low-quality, rotated, handwritten, or unreadable pages should be flagged for human review.
Will it fill in missing information?
No. It can identify missing fields and route them for follow-up, but it should not invent values or present an unsupported inference as extracted data.
Can it preserve where a value came from?
Yes. Source-page, section, or document references can be included in the output when the PDF structure and workflow support that level of provenance.
What is included in the $300/month starting price?
The $300 USD/month starting price covers a scoped, tailored solution. The final proposal defines the extraction workflow, integrations, usage, support, deliverables, and payment terms.