Custom AI agent · Documents & Data
AI Record Matching Agent
Connect the records that describe the same thing.
Compare records across systems, suggest reliable matches and route uncertain pairs for review.
- Match records across approved systems using transparent rules and evidence.
- Reduce duplicate handling without merging uncertain records blindly.
- Give reviewers clear reasons for every suggested match or exception.
Starting at $300 USD/month
Starting price is $300 USD/month. Your final proposal depends on source systems, record volume, matching rules, confidence thresholds, integrations and ongoing support.
What is an AI record matching agent?
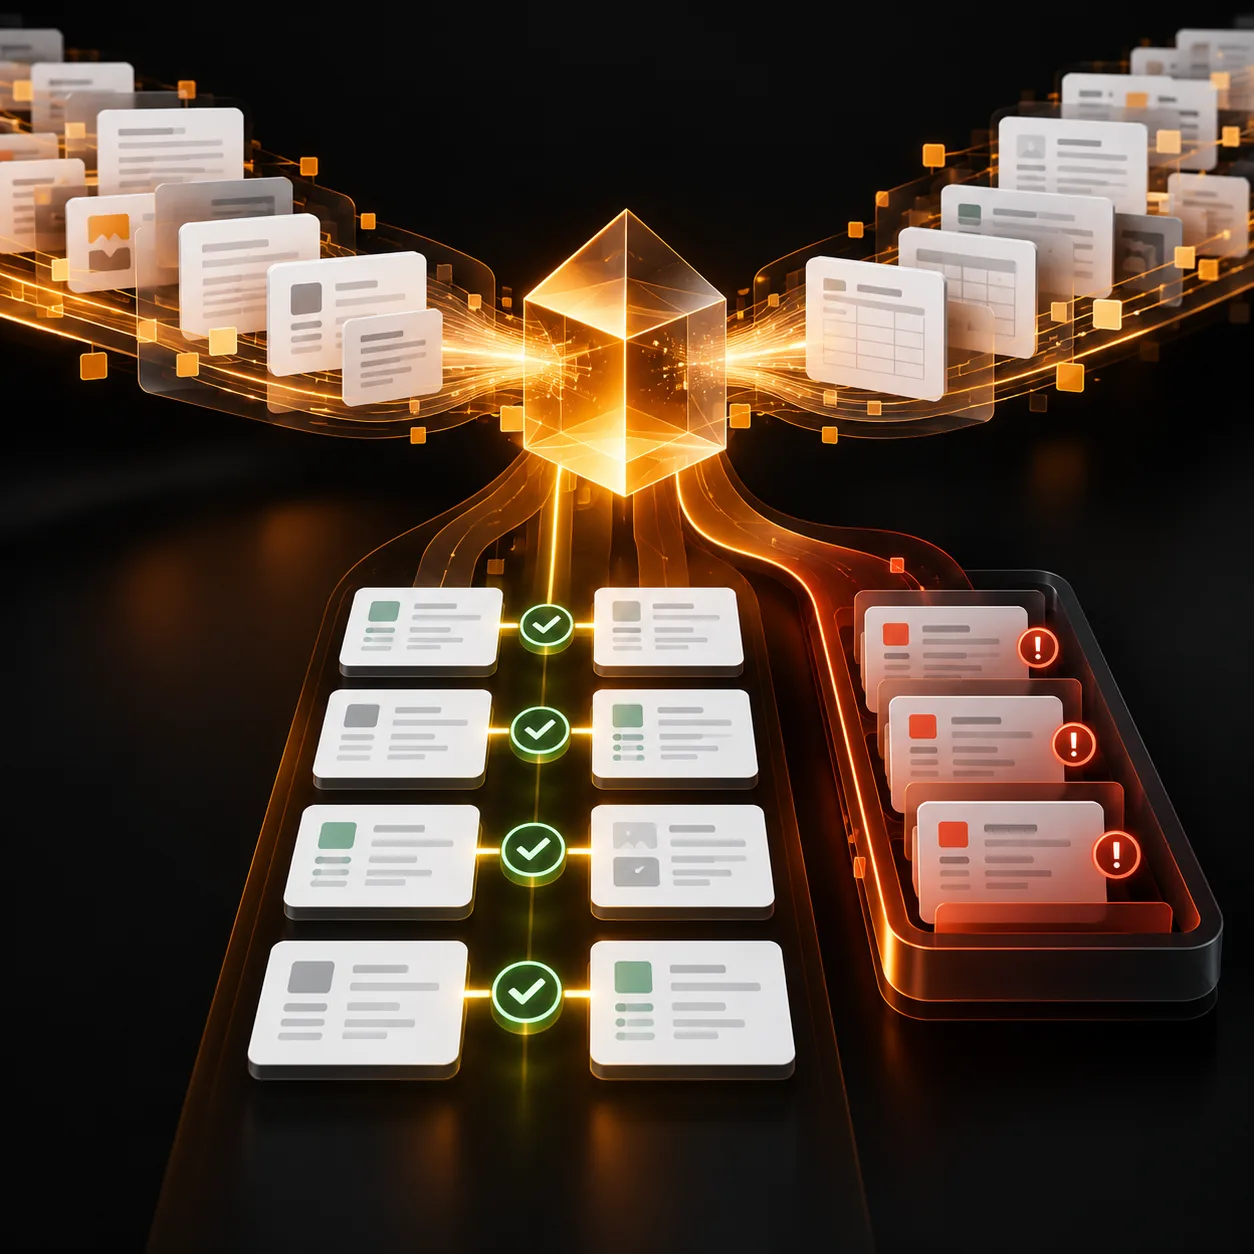
An AI record matching agent compares records that may refer to the same customer, supplier, case, product or other approved entity across structured sources. It combines your chosen identifiers, normalized fields and business rules to rank likely matches, show supporting evidence and separate uncertain or conflicting pairs. Tranki configures the workflow to protect against false merges and preserve an auditable review path.
What it can compare
Normalize matching fields
Standardize approved names, addresses, identifiers, phone numbers, dates and other fields before comparison.
Rank candidate pairs
Compare records using weighted identifiers, exact and fuzzy signals, source priorities and rules you approve.
Explain the match evidence
Show which fields support, weaken or contradict a suggested match so a reviewer can make an informed decision.
Separate uncertain cases
Route low-confidence, conflicting, duplicate or incomplete pairs to a review queue instead of merging them automatically.
Where it can help
Customer and account deduplication
Find likely duplicate customer profiles across CRM, billing, support and marketing sources before records are consolidated.
Supplier and vendor reconciliation
Compare supplier records across procurement, finance and operations systems using approved identifiers and business rules.
Case and entity linking
Connect related cases, applications, products or locations across datasets while keeping ambiguous links visible.
How it works
A step-by-step workflow your team can review before launch.
Define the entity and risk
Agree on what counts as the same entity, which fields are trusted and which false matches would be costly.
Prepare source records
Load approved sources, normalize permitted fields and preserve source identifiers and provenance.
Score and explain candidates
The agent ranks possible matches, documents the evidence and applies your thresholds and exclusion rules.
Review and reconcile
Authorized reviewers confirm, reject or defer pairs before any merge, link or downstream update is applied.
Built around your business
What we configure
- Entity type, source priorities, trusted identifiers, field normalization and language or regional conventions.
- Exact, fuzzy, phonetic, range and cross-field matching rules with configurable weights.
- Confidence thresholds, duplicate groups, exclusion rules, reviewer queues and merge approvals.
- Exports and integrations for CRM, ERP, finance, support, data warehouse or master-data workflows.
What we need from you
- Representative records from each source, including known matches, non-matches and difficult edge cases.
- A defined entity key and the consequences of a false positive versus a missed match.
- Approved fields, source ownership, access rules and the destination for review decisions.
- Named reviewers responsible for confirming merges, maintaining rules and resolving exceptions.
Clear boundaries before launch
What it will not do
The agent does not guarantee identity, merge records without your configured authorization or infer that similar names represent the same person or organization. High-impact identity, compliance, credit, employment or eligibility decisions require appropriate human and organizational controls. Source permissions, retention and sensitive-field handling must be defined before processing.
How success is measured
Measure precision and recall against reviewed samples, false-merge rate, missed-match rate, reviewer agreement, exception volume, time per reviewed pair and the number of duplicate records resolved safely.
Frequently asked questions
What kinds of records can it match?
It can be configured for approved customer, supplier, account, product, case, location or other entity records when the fields and matching objective are clearly defined.
Does it automatically merge duplicates?
Not by default. It can produce ranked suggestions and a review queue; automatic merges require explicit rules, thresholds and authorization in scope.
How does it handle spelling differences?
Approved normalization and fuzzy methods can account for selected spelling, formatting, transliteration or abbreviation differences, with evidence shown to reviewers.
Can it match records across different systems?
Yes, when the sources can be accessed through an approved export or integration and the source identifiers and permissions are defined.
How do we reduce false matches?
We can set trusted-field requirements, exclusion rules, confidence thresholds and human approval gates, then test them against known difficult pairs.
Will it expose sensitive personal information?
Only fields and sources explicitly included in the agreed scope are processed. Access, masking, retention and reviewer permissions should be set with your security and privacy owners.
What does the $300 USD/month starting price include?
It is a starting point for a tailored solution. Final pricing depends on entities, data volume, source systems, matching complexity, review workflows, hosting and support.