Custom AI agent · IT & Security
AI Integration Error Monitoring Agent
Catch integration failures before they become business interruptions.
Monitor the bridges between systems, isolate recurring error patterns, and route actionable fixes with the evidence teams need.
- Earlier visibility into failed, delayed, duplicated, or partially completed integration flows
- Clearer separation of source, destination, authentication, mapping, and dependency failures
- Reviewable error queues that preserve payload context without exposing unnecessary sensitive data
Starting at $300 USD/month
Starting price is $300 USD/month for a tailored solution. Your final proposal defines the integrations, event volume, monitoring scope, deliverables, hosting, support, and payment terms. Additional connectors, retention, or remediation workflows are scoped before work begins.
What is an AI integration error monitoring agent?
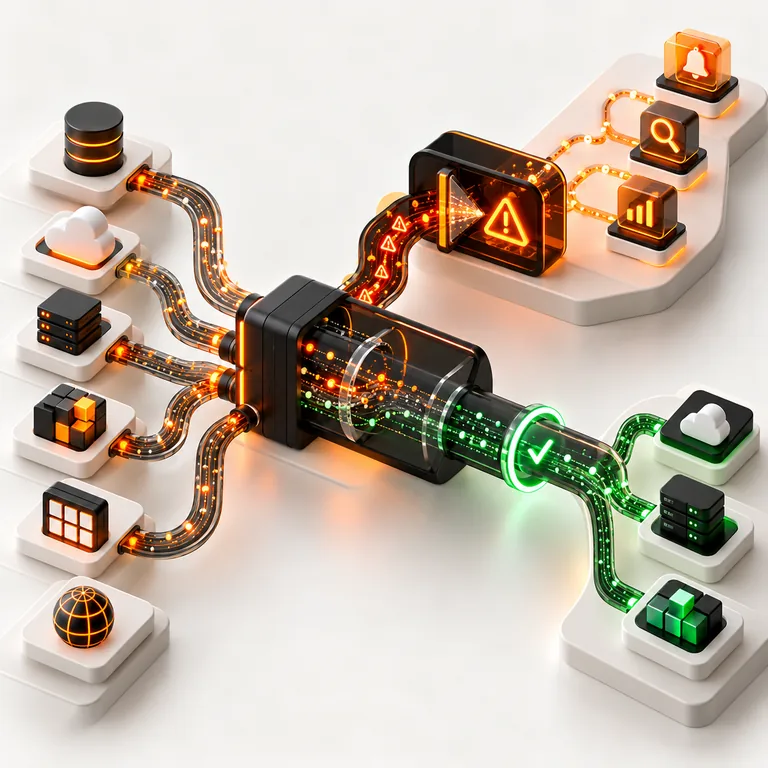
An AI integration error monitoring agent helps operations, engineering, and support teams understand failures that occur between applications, APIs, data pipelines, and workflow platforms. It can correlate connector errors, retries, timeouts, authentication failures, schema mismatches, mapping issues, dependency outages, and delivery gaps; group related events; and route a review-ready case to the right owner. Tranki configures the workflow around your integration catalog, event contracts, severity rules, redaction policy, retry behavior, business impact, and escalation process. The agent improves diagnosis and coordination; it does not replay messages, change credentials, alter mappings, or declare a data transfer complete without authorization and source evidence.
What it can monitor
Correlate integration failures
Compare connector logs, delivery events, retries, response codes, timeouts, queue states, and dependency signals within a defined failure window.
Separate failure domains
Group symptoms by source, destination, connector, authentication, schema, mapping, rate limit, network, or downstream dependency while showing the supporting evidence.
Protect sensitive context
Summarize useful error details, identifiers, and payload structure using configured redaction and retention rules instead of copying full sensitive payloads.
Route actionable follow-up
Prepare an owner-ready case with impact, timeline, affected flows, likely next checks, retry status, and escalation path without making a production change.
Where it can help
Business system integrations
Monitor synchronization between CRM, ERP, finance, support, identity, fulfillment, and collaboration systems where a silent failure can interrupt work.
Data pipeline reliability
Surface delayed, incomplete, duplicated, or rejected transfers across scheduled jobs, event streams, file exchanges, and warehouse loads.
Partner and customer workflows
Give teams a consistent way to assess connector errors, affected records, and customer or partner impact before communicating a resolution.
How it works
A step-by-step workflow your team can review before launch.
1. Define the integration map
Tranki maps source and destination systems, connectors, event contracts, owners, dependencies, severity, redaction, retry, and escalation rules.
2. Gather approved error signals
The agent reads permitted logs, delivery events, queue state, response metadata, tickets, deployments, and status sources while preserving timestamps and links.
3. Group and explain the failure
It identifies related errors, likely failure domains, affected flows, missing evidence, and business impact while distinguishing observations from hypotheses.
4. Review and recover safely
An authorized owner decides whether to retry, replay, correct, or escalate through existing controls; the agent records the outcome and unresolved work.
Built around your business
What we configure
- integration catalog, source and destination owners, connectors, event contracts, schemas, mappings, dependencies, retry rules, rate limits, severity, business impact, and escalation
- connections to approved integration, API, queue, workflow, logging, monitoring, ticketing, deployment, status, and reporting systems using least-privilege access
- error taxonomy, redaction patterns, retention, notifications, languages, incident templates, review queues, runbook links, and post-failure reporting
What we need from you
- an integration inventory, connector ownership, event or schema definitions, approved error sources, retry policy, impact model, escalation paths, and representative failures
- authenticated access to permitted integration, API, queue, logging, monitoring, ticketing, deployment, and reporting systems with privacy and retention controls
- test cases covering authentication failures, timeouts, rate limits, schema drift, mapping errors, partial delivery, duplicates, dependency outages, sensitive payloads, and recovery
Clear boundaries before launch
What it will not do
The agent does not replay events, modify mappings, rotate credentials, change rate limits, delete failed records, or declare data delivered without authorized human review and system controls. It should not expose secrets or full sensitive payloads, treat a successful API response as proof of downstream processing, infer business impact from an error count alone, or merge unrelated failures. Financial, regulated, security-sensitive, customer-impacting, and irreversible recovery actions require the appropriate owners.
How success is measured
Track failure-detection freshness, classification agreement, time to owner-ready case, duplicate-group precision, redaction compliance, false-escalation rate, unresolved-error age, retry and recovery outcome visibility, affected-flow coverage, source-link completeness, and human correction rate. Sample summaries against raw connector and delivery evidence to verify observed facts, affected scope, and failure-domain labels.
Frequently asked questions
What does an AI integration error monitoring agent do?
It correlates approved integration signals, groups related failures, identifies likely failure domains, summarizes impact, and routes a reviewable case to the right owner.
Can it retry or replay failed messages automatically?
Not by default. It can show retry status and prepare a recommended next step, while an authorized owner controls replay or recovery through existing safeguards.
Can it monitor APIs, queues, and workflow platforms?
Yes, when those systems are approved and connected. The workflow can combine delivery events, logs, response metadata, queue state, and related tickets.
How does it handle sensitive payloads?
It can use configured redaction, minimization, access, and retention rules so teams receive useful diagnostics without copying unnecessary sensitive content.
Can it tell whether an error affected customers?
It can summarize impact when approved customer, record, or business-context signals are available. It should label uncertainty rather than infer impact from volume alone.
What happens when a schema or mapping changes?
The agent can flag schema or mapping-related failures, preserve the evidence, and route the case to the integration owner or change process you define.
What is included in the $300/month starting price?
The starting price covers a scoped, tailored solution. The final proposal defines integrations, event volume, retention, deliverables, support, hosting, and payment terms.